NOW BUZZING 어그가 로퍼를 만든 이유, JW 앤더슨과… · 유니클로가 '다크 아카데미아'를 입기 쉽… · 리미 푸가 스케이트보드를 옷처럼 파는 법◆
JELIBI
⌕ SUBSCRIBE
SEOUL · DAILY · ISSUE No.340 WE TRIED IT · THE PICK · BEHIND IT 2026.10.13 · TUE
JELIBI
⌕ SUB
Beauty Body Gadget Bites Buzz World
HOME/GADGET/BEHIND IT
GADGET BEHIND IT · 5 MIN READ

NVIDIA, AI 추론 소프트웨어 Dynamo 공개
JD 젤리비 편집국 · 2025.07.03 SHARE · COPY LINK

무슨 발표인가

  • Triton Inference Server의 후속 오픈소스 추론 소프트웨어
  • 수천 개 GPU 규모의 추론 통신 오케스트레이션·가속화
  • 처리·생성 단계를 분리해 각 단계별 독립 최적화 가능

현재 이용 가능

원문 (영어)

GTC— NVIDIA today unveiled NVIDIA Dynamo , an open-source inference software for accelerating and scaling AI reasoning models in AI factories at the lowest cost and with the highest efficiency. Efficiently orchestrating and coordinating AI inference requests across a large fleet of GPUs is crucial to ensuring that AI factories run at the lowest possible cost to maximize token revenue generation.

As AI reasoning goes mainstream, every AI model will generate tens of thousands of tokens used to “think” with every prompt. Increasing inference performance while continually lowering the cost of inference accelerates growth and boosts revenue opportunities for service providers.

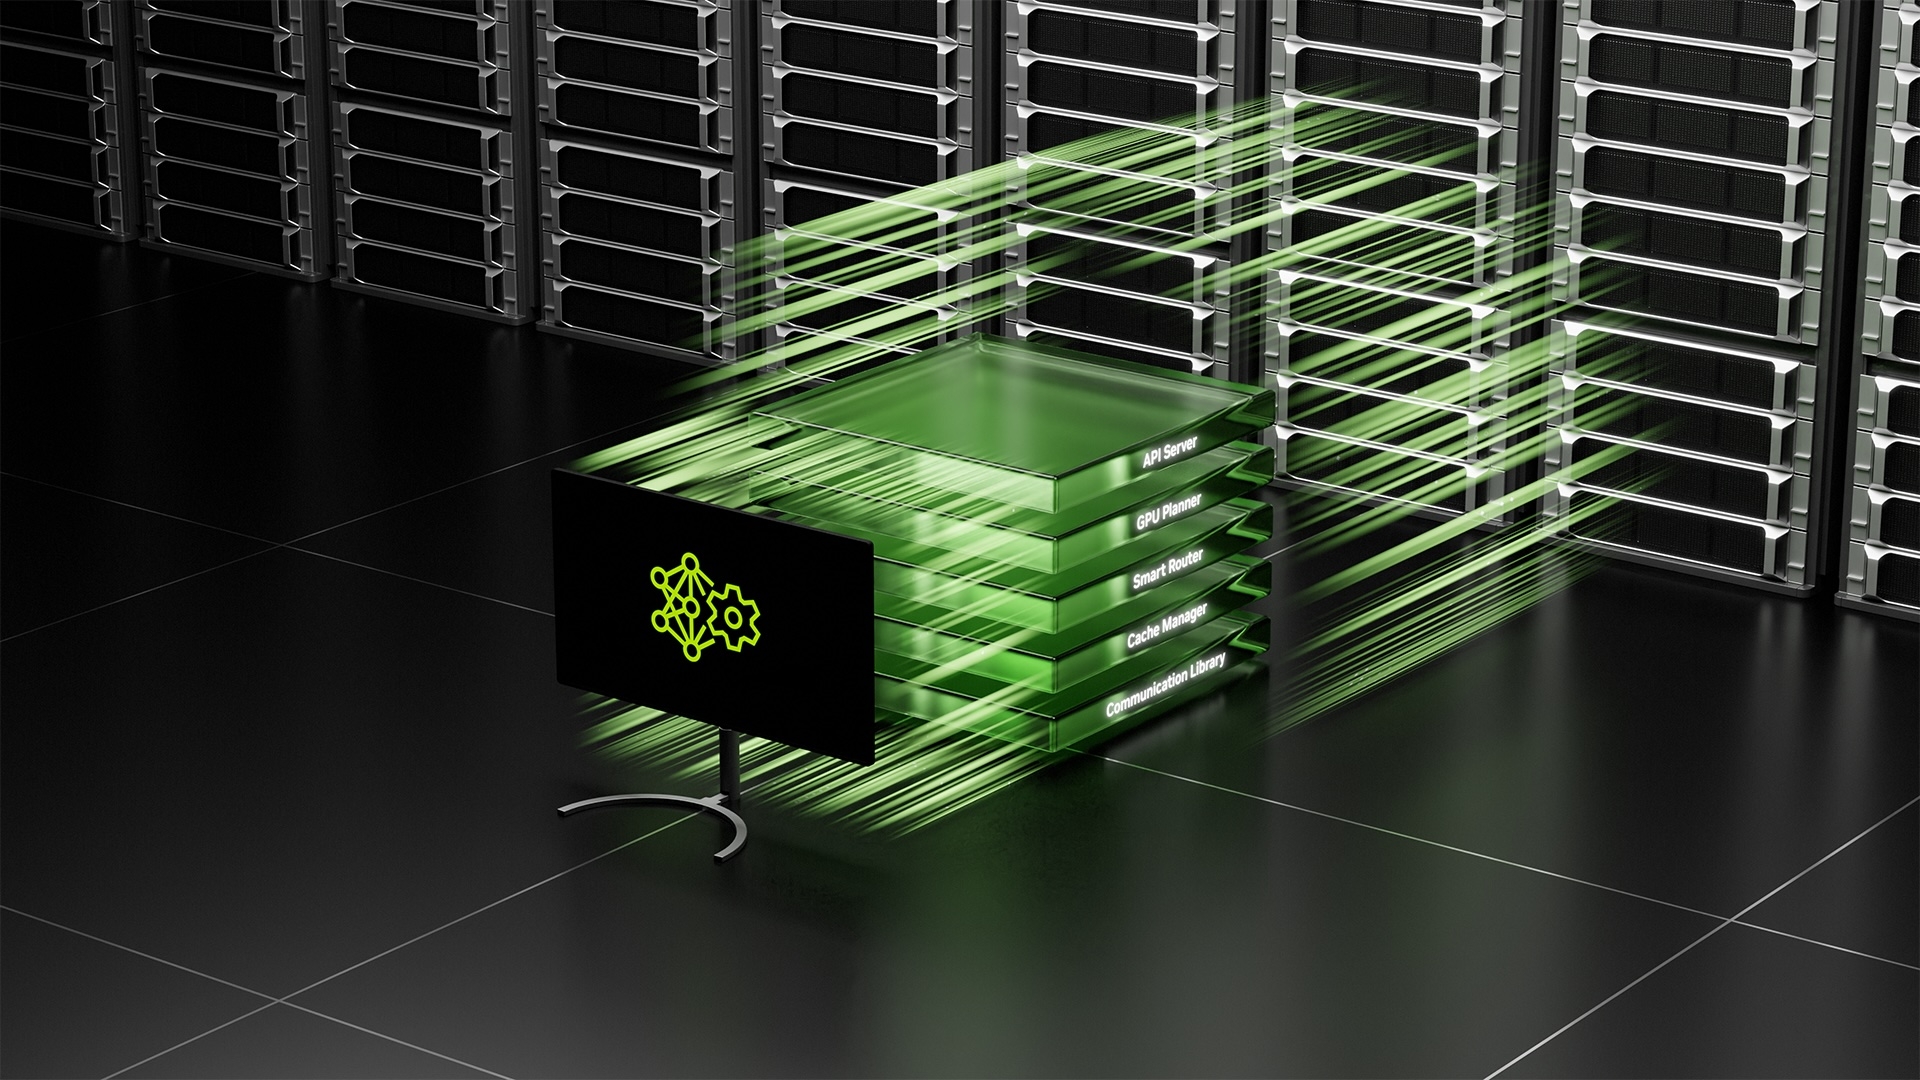
NVIDIA Dynamo, the successor to NVIDIA Triton Inference Server , is new AI inference-serving software designed to maximize token revenue generation for AI factories deploying reasoning AI models. It orchestrates and accelerates inference communication across thousands of GPUs, and uses disaggregated serving to separate the processing and generation phases of large language models (LLMs) on different GPUs.

This allows each phase to be optimized independently for its specific needs and ensures maximum GPU resource utilization. “Industries around the world are training AI models to think and learn in different ways, making them more sophisticated over time,” said Jensen Huang, founder and CEO of NVIDIA.

“To enable a future of custom reasoning AI, NVIDIA Dynamo helps serve these models at scale, driving cost savings and efficiencies across AI factories.” Using the same number of GPUs, Dynamo doubles the performance and revenue of AI factories serving Llama models on today’s NVIDIA Hopper platform.

원문: NVIDIA News — "NVIDIA Dynamo Open-Source Library Accelerates and Scales AI Reasoning Models" (2025-07-03) 공식 원문: https://nvidianews.nvidia.com/news/nvidia-dynamo-open-source-library-accelerates-and-scales-ai-reasoning-models

#NVIDIA News
THE JELIBI BRIEF

A small team that reads too much internet so you don't have to.
SUBSCRIBE →
GADGET

오픈소스 취약점 스캔 서비스 OSS Scanner 무료 출시

GADGET

메타, 싱가포르 장애인을 위해 AI 안경 1000개 기부

GADGET

삼성전자 2026년 3분기 영업이익 107.4조 원 발표

← GADGET BEHIND IT

NVIDIA, AI 추론 소프트웨어 Dynamo 공개

젤리비 편집국·2025.07.03·5 MIN
IN THIS PIECE
무슨 발표인가 원문 (영어)

무슨 발표인가

  • Triton Inference Server의 후속 오픈소스 추론 소프트웨어
  • 수천 개 GPU 규모의 추론 통신 오케스트레이션·가속화
  • 처리·생성 단계를 분리해 각 단계별 독립 최적화 가능

현재 이용 가능

원문 (영어)

GTC— NVIDIA today unveiled NVIDIA Dynamo , an open-source inference software for accelerating and scaling AI reasoning models in AI factories at the lowest cost and with the highest efficiency. Efficiently orchestrating and coordinating AI inference requests across a large fleet of GPUs is crucial to ensuring that AI factories run at the lowest possible cost to maximize token revenue generation.

As AI reasoning goes mainstream, every AI model will generate tens of thousands of tokens used to “think” with every prompt. Increasing inference performance while continually lowering the cost of inference accelerates growth and boosts revenue opportunities for service providers.

NVIDIA Dynamo, the successor to NVIDIA Triton Inference Server , is new AI inference-serving software designed to maximize token revenue generation for AI factories deploying reasoning AI models. It orchestrates and accelerates inference communication across thousands of GPUs, and uses disaggregated serving to separate the processing and generation phases of large language models (LLMs) on different GPUs.

This allows each phase to be optimized independently for its specific needs and ensures maximum GPU resource utilization. “Industries around the world are training AI models to think and learn in different ways, making them more sophisticated over time,” said Jensen Huang, founder and CEO of NVIDIA.

“To enable a future of custom reasoning AI, NVIDIA Dynamo helps serve these models at scale, driving cost savings and efficiencies across AI factories.” Using the same number of GPUs, Dynamo doubles the performance and revenue of AI factories serving Llama models on today’s NVIDIA Hopper platform.

원문: NVIDIA News — "NVIDIA Dynamo Open-Source Library Accelerates and Scales AI Reasoning Models" (2025-07-03) 공식 원문: https://nvidianews.nvidia.com/news/nvidia-dynamo-open-source-library-accelerates-and-scales-ai-reasoning-models

#NVIDIA News
THE JELIBI BRIEF

A small team that reads too much internet so you don't have to.
SUBSCRIBE →
MORE IN BEHIND IT
CJ ENM, 베트남 극장가 15년 점유 — TOP5 중 3편 참여H&M·IKEA, 재활용 섬유 화학 오염 대규모 연구 결과 발표CGV, 진격의 거인 극장판 3편 순차 개봉 — SCREENX·4DX 동시 상영CJ대한통운 AI 물류플랫폼 '더 운반' 기업 공략…10월 운임 50% 할인오픈소스 취약점 스캔 서비스 OSS Scanner 무료 출시
THE JELIBI BRIEF

인터넷을 너무 많이 보는 팀이 대신 골라 옵니다.

SUBSCRIBE

바로가기 등록하시면, 더 쉽게 찾아보실 수 있습니다.